AI Token Counter & API Cost Estimator
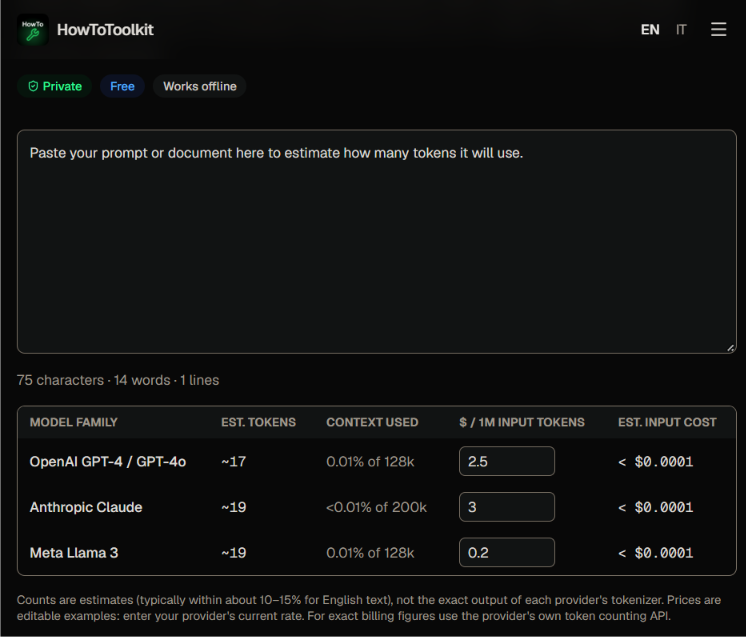
Paste a prompt, document or code snippet and get an instant token estimate for OpenAI GPT-4 and GPT-4o, Anthropic Claude and Meta Llama models, along with how much of each context window you are using. Enter the current price per million tokens and the tool shows the estimated input cost. Everything is computed locally in your browser, so private prompts are never uploaded.
Reviewed by Vincenzo Manto, Founder & Lead Developer · Last updated September 30, 2026
How it works
- 1
Paste your prompt, document or code into the text box.
- 2
Read the estimated token count for each model family and the share of the context window it uses.
- 3
Edit the price per million tokens to match your provider and see the estimated input cost.
Screenshots
Example
The quick brown fox jumps over the lazy dog.GPT-4 / GPT-4o: ~10 tokens
Claude: ~10 tokens
Llama 3: ~10 tokensWhy count tokens
Language model APIs bill per token and limit how many tokens fit in a request, so knowing the size of a prompt before sending it avoids surprises. Counting helps you decide whether a document fits a context window, how much a batch of calls will cost, and whether trimming boilerplate from a prompt is worth the effort.
Tips for reducing token usage
Remove repeated instructions and unneeded whitespace, prefer concise phrasing, and send only the relevant part of long documents instead of the whole file. Non-English text and code often use more tokens per character than English prose, so budget extra. Caching a long shared prefix, where your provider supports it, can also cut cost.
Frequently asked questions
How accurate are the counts?
They are estimates, usually within roughly 10–15% for English prose. Exact counts depend on each provider's tokenizer vocabulary. Code, unusual symbols and non-Latin scripts vary more. For billing-grade numbers use the provider's official token counting endpoint.
Why not use the official tokenizers?
Vocabularies are large files and Anthropic's tokenizer is not published. An estimator keeps the page light, instant and fully offline, which is enough for budgeting and checking that a prompt fits a context window.
What is a token?
A token is a chunk of text a language model reads as one unit: a short word, part of a longer word, a number fragment or punctuation. In English, one token is about four characters or three quarters of a word.
Are prices built in?
The price fields hold example values that you can edit. Provider pricing changes often, so type the current input price from your provider's pricing page. Output tokens are billed separately and usually cost more.
Related tools
AI Music Sanitizer
Strip metadata and ultrasonic AI signatures from audio tracks.
AI Image Sanitizer
Strip prompts, metadata and Content Credentials from AI-generated images.
JSONL Validator & Converter (CSV, JSON ↔ JSONL)
Validate JSON Lines files for AI fine-tuning and convert between JSONL, CSV and JSON arrays.